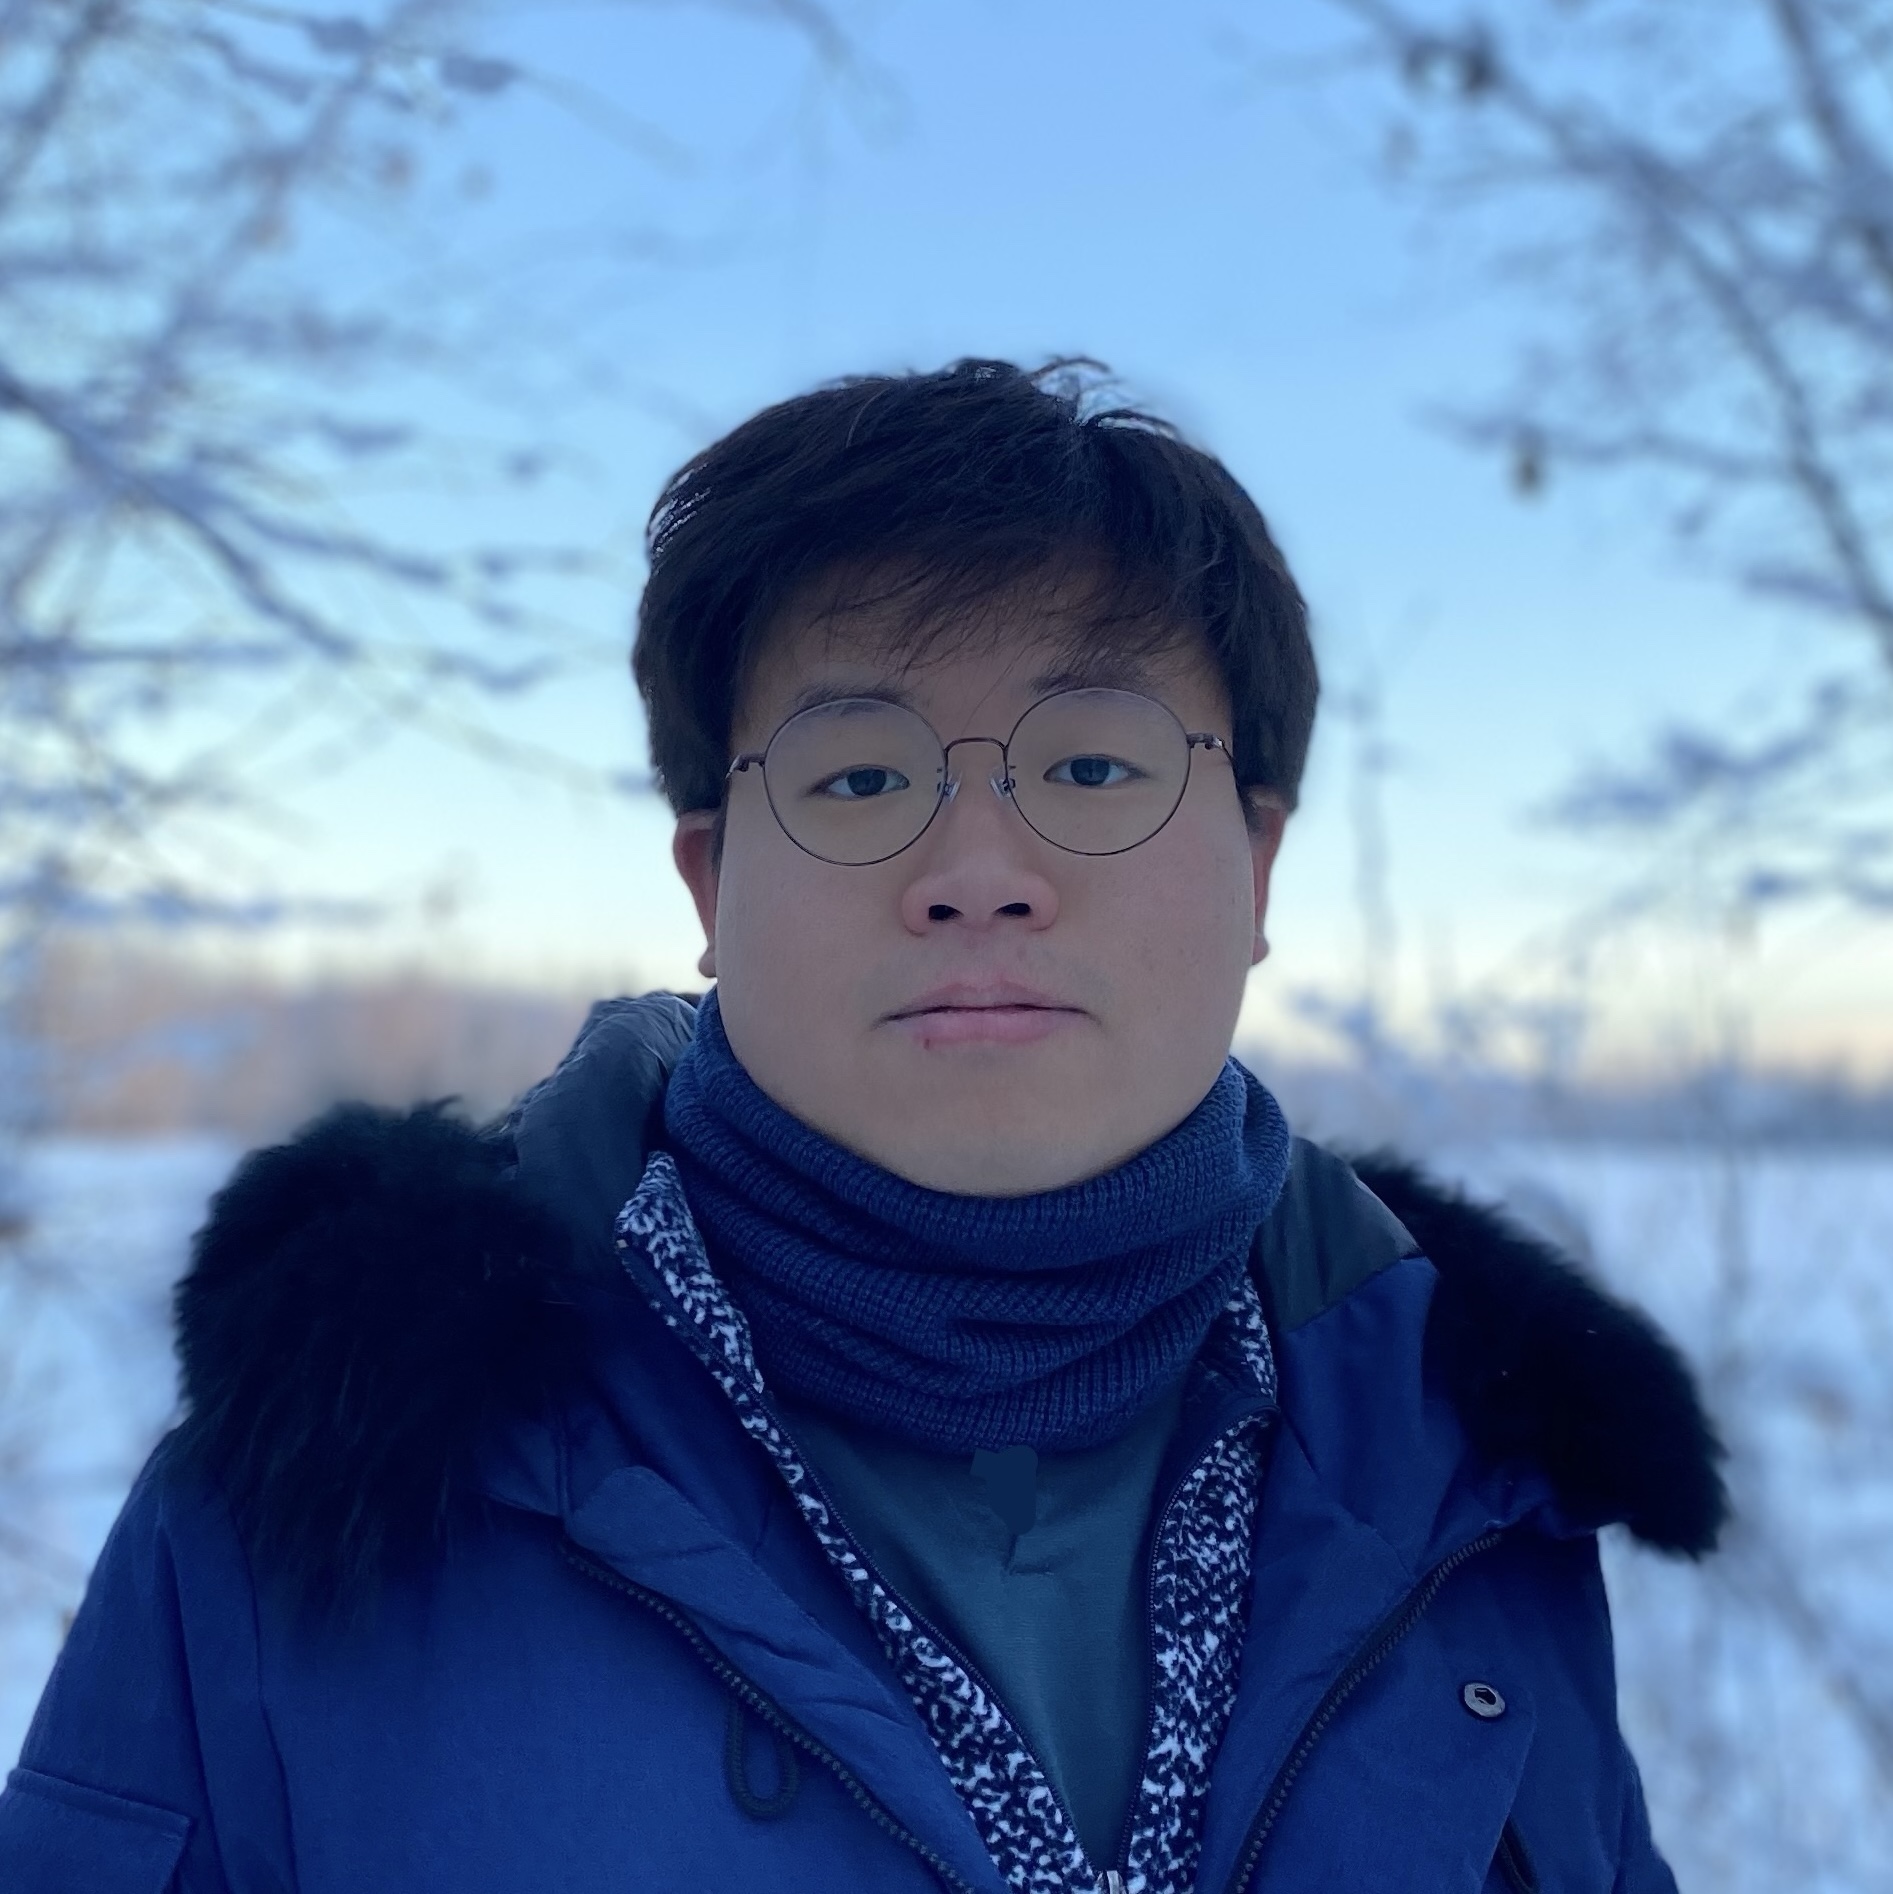
About
Physical Design Engineer, Machine Learning @ Apple. Theoretical High Energy Physics PhD, Caltech (2025).
Working at the intersection of physics and AI — ML for chip design, reinforcement learning for quantum gravity, and autonomous research systems.
What I Do
I’m a Physical Design Engineer (Machine Learning) at Apple (since October 2025). I completed my Ph.D. in theoretical high energy physics at Caltech in September 2025. I work at the intersection of physics and AI, in both directions: using modern ML as a search engine over mathematical structures, and building AI systems that can do research with human taste. Current threads:
- ML for Physics & Mathematics: Reinforcement learning for the holographic entropy cone, transformers for symbolic algebra (BGRPO), AlphaZero-style self-play for combinatorial bounds
- Autonomous Research Systems: Agentic research loops with structural honesty (falsifiable experiment cards) and kkanbu — a preference oracle that holds a researcher’s taste as a typed knowledge graph
- LLM Training & Fine-tuning: GRPO/PPO/DPO, rank-aware RL for beam search, self-play training
- AI Safety: Jailbreak analysis, automated red-teaming, representation engineering
Recent Work
Exploring the Holographic Entropy Cone via RL (JHEP 2026)
With Temple He and Hirosi Ooguri. An RL algorithm that searches for graph realizations of entropy vectors — resolving the status of “mystery” extreme rays of the N=6 cone and implying unknown holographic entropy inequalities exist. Post · arXiv:2601.19979
An AI Scientist that Doesn’t Drift (ICML 2026 AI for Science Workshop)
Autonomous research loops for quadruped robot navigation, run as a controlled ablation with and without kkanbu, our taste oracle. The scaffold keeps the loop honest; kkanbu decides where it looks. Post · arXiv:2608.07542
Rank-Aware Beam GRPO for Polynomial Decomposition (TMLR)
Transformers discovering hidden algebraic structures, with a novel rank-aware RL method cutting inference compute ~75%. Outperforms Mathematica in various simplification cases. Post · arXiv:2508.15766
Multi-Turn Jailbreaks Are Simpler Than They Seem (COLM 2025 SoLaR Workshop)
Multi-turn jailbreaking is approximately equivalent to resampling single-turn attacks — with implications for safety evaluation. Post · arXiv:2508.07646
Earlier
- Research Internship at Morph Labs (Jan–Mar 2025): RL for tool use and reasoning; imitation learning and policy optimization pipelines on coding benchmarks
- Angular fractals in thermal QFT with N. Benjamin, S. Pal, D. Simmons-Duffin, Y. Xu (arXiv:2405.17562)
Publications & Recognition
- Physics: Papers in high-energy physics including JHEP 2026 (holographic entropy cone via RL), thermal QFT angular fractals, Conformal Field Theory, and Kerr-AdS superradiant instability
- ML/AI: TMLR (BGRPO), ICML 2026 AI4Science workshop (AI scientist / kkanbu), COLM 2025 SoLaR workshop (multi-turn jailbreaks)
- Gold Medal: International Physics Olympiad (2013)
- James A. Cullen Memorial Fellowship: Caltech (2021)